Architectural Bottlenecks in Cloud Stream Chunking
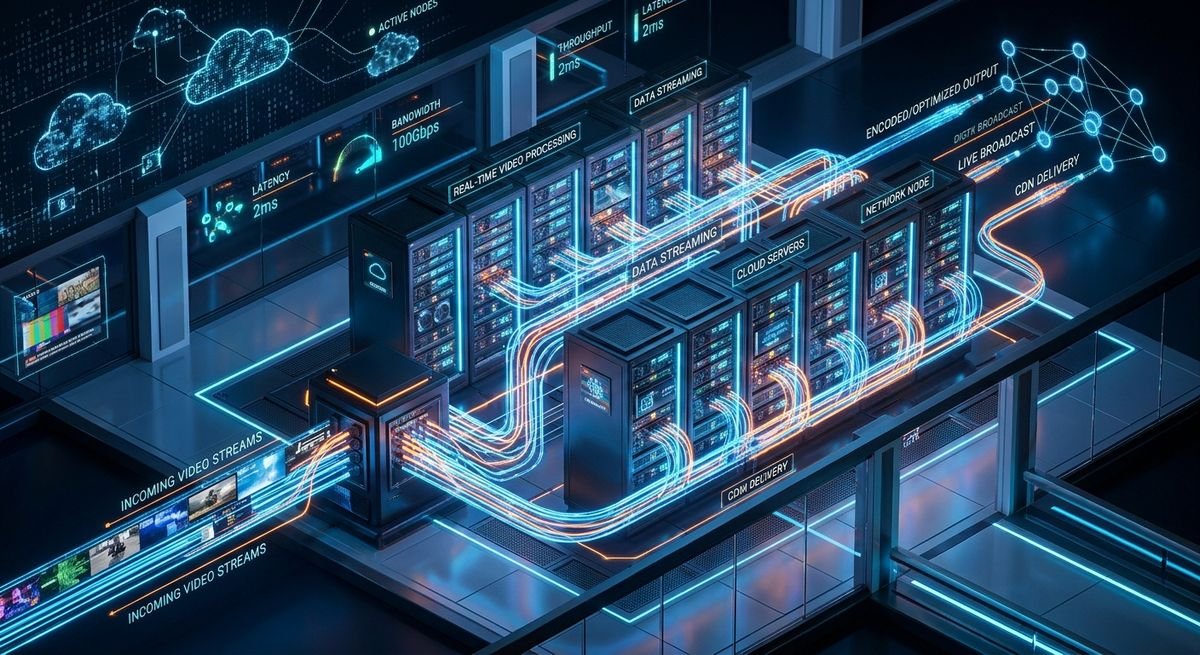
I built a real-time frame extraction pipeline for live video backends last year. We processed incoming HLS video chunks through serverless functions. However, p99 latency quickly spiked above two seconds. Cold starts severely hampered overall response times. In video streaming, every millisecond counts. Users experience buffering whenever processing pipelines stutter.
Reducing Function Execution Overhead for Fast Transcoding
We identified two main latency bottlenecks in our serverless architecture. First, runtime container initialization took 800ms on cold starts. Second, heavy binary dependencies bloated our deployment package size. Consequently, standard memory allocation throttled CPU performance. We required execution times under 200ms per segment. Therefore, default cloud function configurations proved completely insufficient for our real-time throughput targets.
Implementation Patterns for Function Cold Start Reduction
We applied Serverless latency optimization by switching to provisioned concurrency alongside custom compiled runtimes. First, we stripped unnecessary audio codecs out of our native binaries. Next, we built a lightweight Rust wrapper around frame processing logic. Consequently, this step reduced our total package size from 120MB to 14MB. Initialization overhead dropped instantly.
Here is the routing setup we deployed to handle stream chunks:
{
  "TargetFunction": "arn:aws:lambda:us-east-1:123456789012:function:frame-processor",
  "ProvisionedConcurrency": 10,
  "PayloadFormat": "JSON_STREAM"
}
In addition, we routed memory streams directly to AWS S3 Express One Zone to eliminate disk bottlenecks. Serverless latency optimization requires eliminating disk I/O operations entirely.
pub async fn process_chunk(chunk: &[u8]) -> Result<Vec<u8>, Error> {
    let decoded = decode_h264_frame(chunk)?;
    Ok(transform_matrix(decoded))
}
Stream Processing Latency Metrics and Lessons Learned
Our load test metrics demonstrated massive performance gains across all operational benchmarks. Average processing latency dropped from 1800ms down to 140ms. System throughput safely expanded to handle over 500 concurrent camera streams without dropping a single frame. We continuously monitor telemetry metrics to detect runtime drift quickly. Early detection prevents compounding stream delays.
Here are vital production considerations for high-throughput video pipelines:
- Keep binary dependencies minimal by compiling lean micro-runtimes tailored to specific video codecs.
- Avoid ephemeral disk writes completely by utilizing in-memory streaming channels for segment processing.
- Implement provisioned concurrency patterns to prevent unexpected cold start latency spikes during traffic surges.
- Benchmark execution runtime memory to optimize CPU core allocations dynamically.
For more architectural deep dives, visit our blog section. If you require expert cloud engineering guidance, email us at contact@klubhub.click. Maintaining high performance requires continuous Serverless latency optimization across all microservices.